The Challenge of Human-Like Abstraction in Contemporary AI
Abstract
Contemporary AI models have matched or exceeded human performance on many benchmarks meant to assess general human-like reasoning abilities, including the prominent Abstraction and Reasoning Corpus (ARC). However, it is often unclear whether these models achieve high accuracy by reasoning with the abstractions these benchmarks were designed to evaluate, or through other non-human-like strategies that focus on surface-level patterns. Here, we articulate cognitive-science-inspired evaluation principles to investigate the abstraction abilities of AI models and human participants. As a case study, we use ConceptARC, a benchmark in the ARC domain that assesses abstract reasoning using isolated “core-knowledge” concepts. In addition to measuring accuracy, we evaluate the natural-language rules that models and humans generate to explain their solutions, allowing us to distinguish between solutions using intended abstractions and those relying on surface-level patterns. While some models exceed human accuracy on textual versions of the tasks, their rules are substantially less likely than human-generated rules to capture intended abstractions. When given visual inputs, the accuracy of these models decreases dramatically; in numerous cases they are able to abstract a correct rule but fail to apply it to form a correct output. These findings illustrate that evaluations based on accuracy alone are not reliable indicators of a model's general capabilities, and that humans still exhibit a greater propensity for abstract reasoning than AI models. The evaluation principles we articulate can provide a more rigorous assessment of AI models' capabilities than measures based solely on accuracy.
Significance
As humans increasingly interact with and rely on artificial intelligence, it is imperative to properly evaluate AI's capabilities and limitations. Typical AI studies report only accuracy—the fraction of correct answers—on tests developed to assess particular capabilities. However, such evaluation methods can be misleading: when an AI system gets the right answers for the wrong reasons, it cannot reliably generalize. Here, we articulate evaluation principles for more deeply assessing general capacities in humans and machines. Adopting these principles to investigate abstract reasoning abilities in state-of-the-art AI models, we find that previous evaluations have overestimated these models' ability to form concepts and reason in a human-like way. Such systems are still missing core capabilities underlying human intelligence.
Evaluation principles from cognitive science
We adopt three principles that cognitive scientists have proposed for evaluating cognitive capacities in AI systems.
Test for robustness, not only accuracy
Test the same conceptual abstraction across multiple tasks and measures, so that success depends on the general capacity rather than on properties of particular stimuli.
Investigate possible shortcuts
Consider alternative strategies a model might use to reach the correct answer, and design controls that tell these strategies apart.
Separate performance from competence
Success in a limited setting can overstate a general capacity, while system-specific limitations, such as perception, can understate it.
ConceptARC
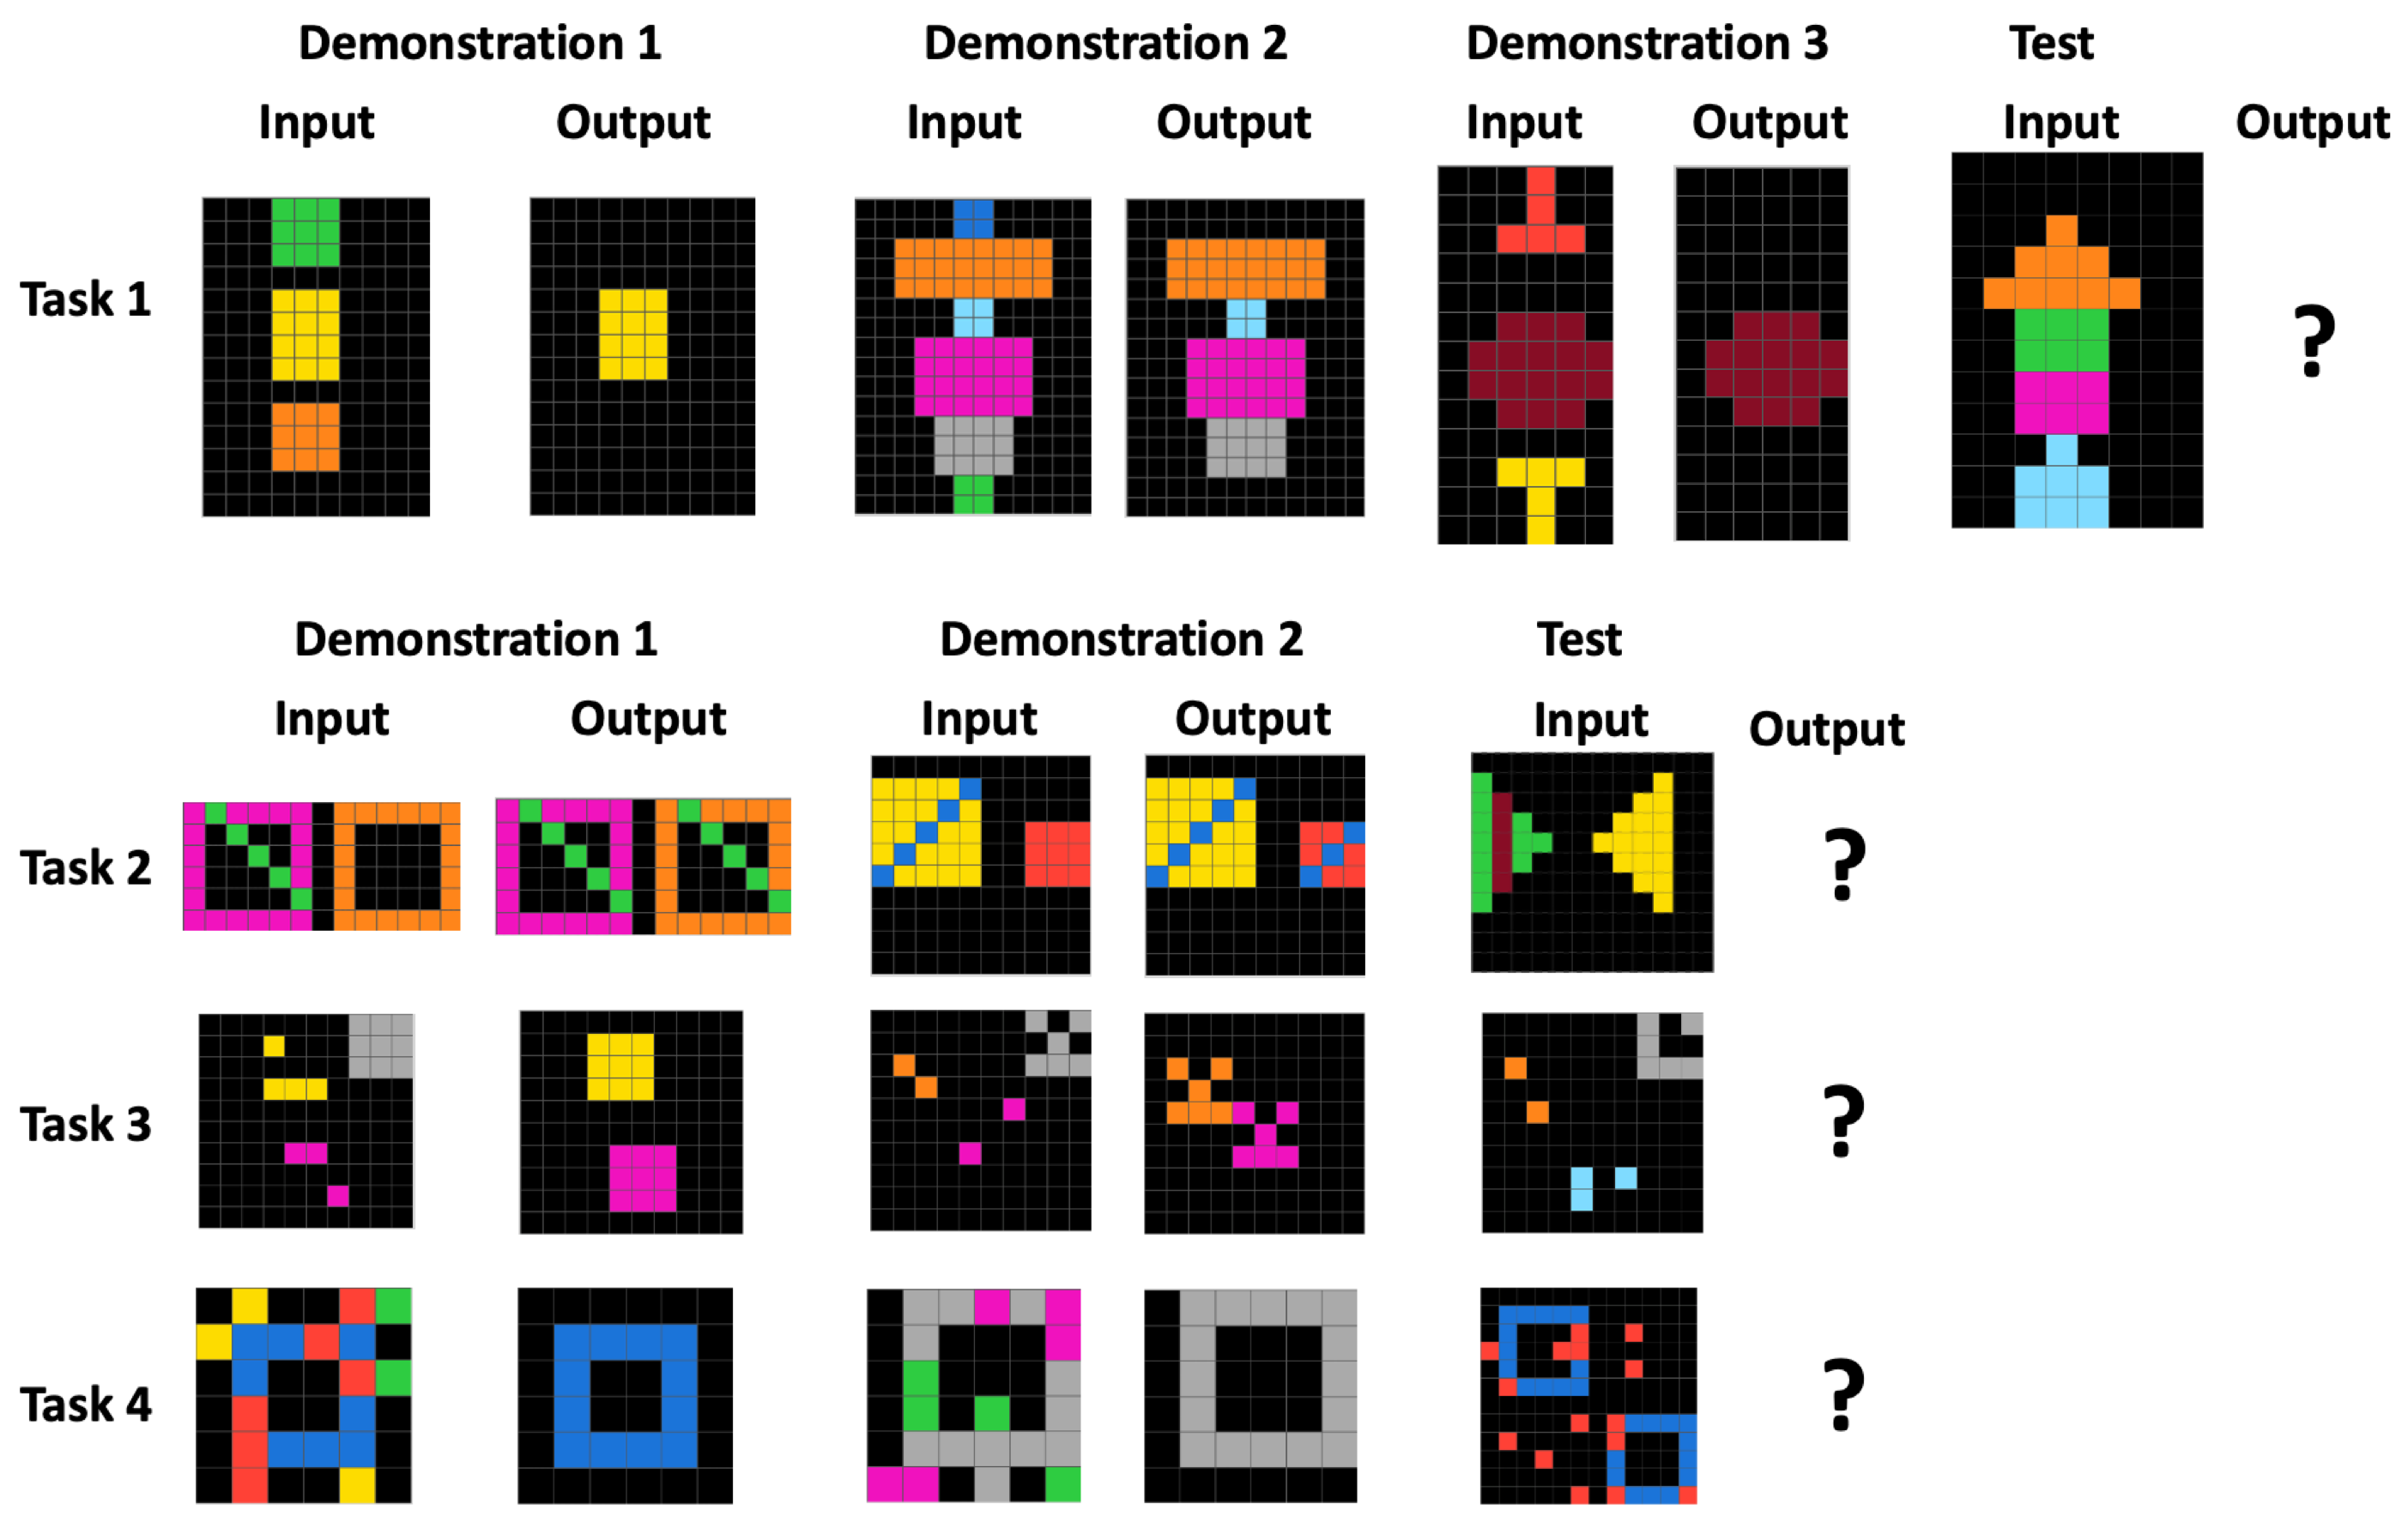
ConceptARC contains 480 tasks in the ARC domain, each focused on one of 16 basic spatial and semantic concepts such as “inside and outside”, “above and below” and “same vs. different”, with 30 tasks per concept. The tasks are designed to be easy for humans, so they test whether a solver grasps the concept rather than how hard the puzzle is.
Key findings
We evaluated o3, Claude Sonnet 4 and Gemini 2.5 Pro with textual and visual inputs, and compared their output grids and the natural-language rules they stated with those of human participants.
Output-grid accuracy
| Model | Textual | Visual |
|---|---|---|
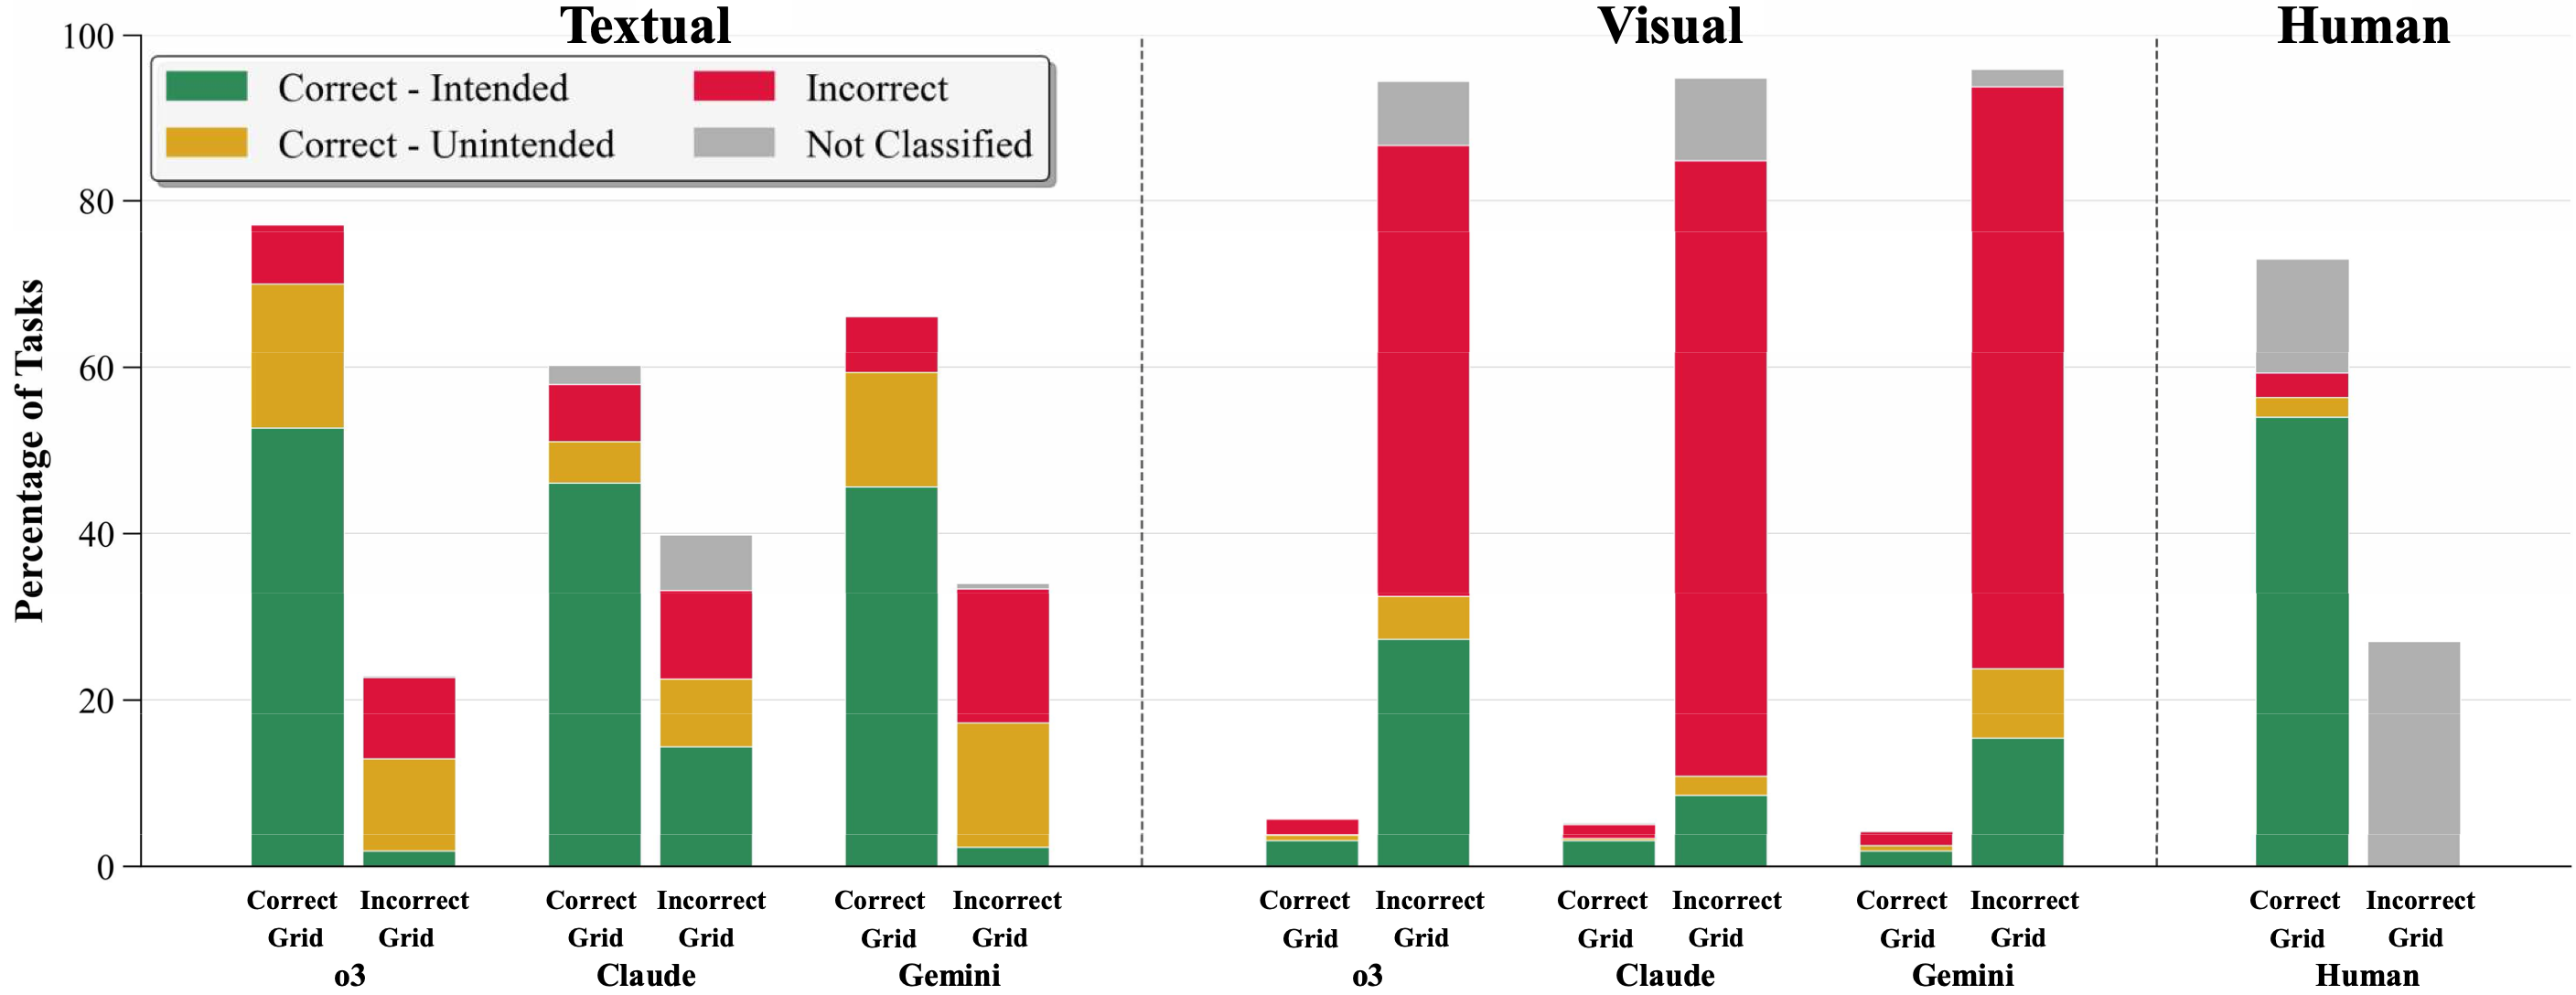
| o3 | 77.1 | 5.6 |
| Claude Sonnet 4 | 60.2 | 5.2 |
| Gemini 2.5 Pro | 66.0 | 4.2 |
| Humans | N/A | 73.0 |
Pass@1 accuracy (%) on the 480 ConceptARC tasks. Humans were tested only with visual inputs.
Accuracy overstates competence with textual inputs and understates it with visual inputs
Each rule was classified as correct-intended (it captures the intended abstraction), correct-unintended (it works on the demonstrations but relies on unintended features) or incorrect. With textual inputs, a sizeable share of the models' correct outputs rest on rules that miss the intended abstraction. With visual inputs, the models often state the intended rule but fail to apply it.
Humans describe objects, models describe grids
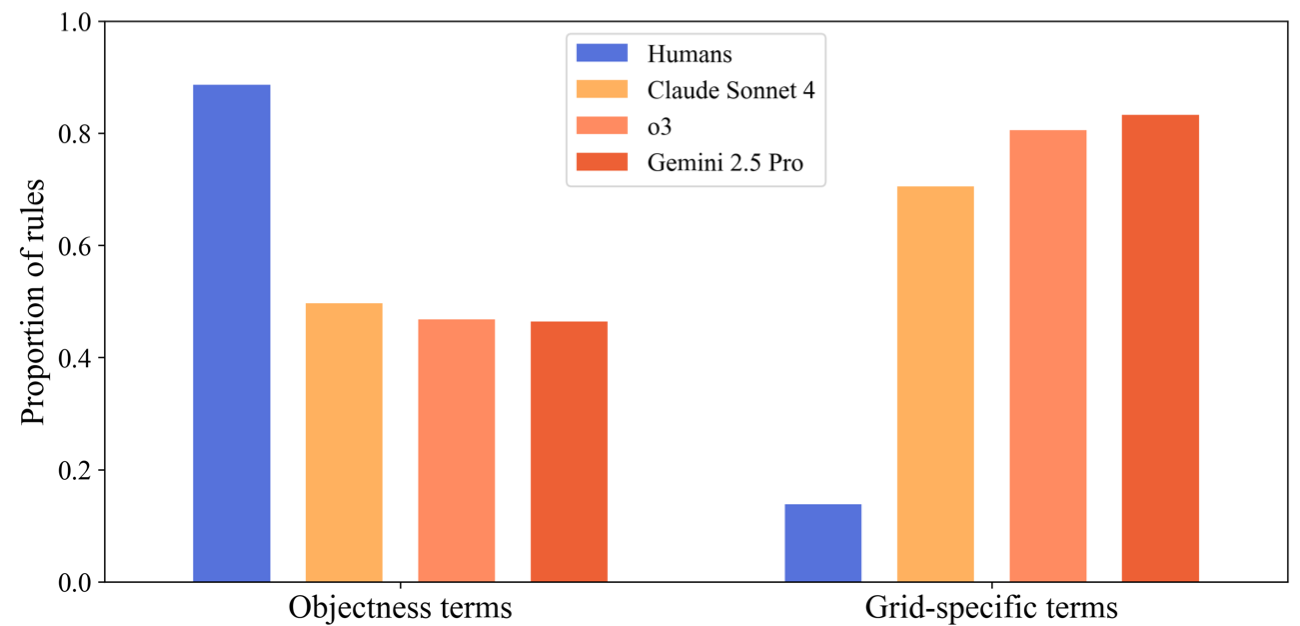
ConceptARC builds on core-knowledge concepts such as objectness. Human rules mostly refer to objects, while the models' rules mostly refer to individual cells, rows, columns and other low-level features of the grid.
Dataset viewer
Use this viewer to investigate model and human responses on the ConceptARC tasks.
Full data can be downloaded from ClaasBeger/HumanLikeARCAbstraction on Hugging Face.